AI24 Sept 2026
Adobe buys Topaz Labs: the licence question
Adobe closed its $340M Topaz Labs purchase on 23 September. Topaz keeps its own brand, and nothing was said about what the standalone apps will cost.
Generative tools where they touch a working pipeline — what they take off an artist’s plate, what they quietly add to it, and which claims survive contact with a deadline.
14 articles · latest 24 Sept 2026
Adobe closed its $340M Topaz Labs purchase on 23 September. Topaz keeps its own brand, and nothing was said about what the standalone apps will cost.
Japan's industry body puts generative AI use at 85.8%, up from 51%. The task breakdown comes from a far smaller sample, and puts visuals near the bottom.
Akihiro Hino apologised for AI in Level-5's Vision 2026 II broadcast, then restated the plan: turn artwork into polygons, five-year projects into two.
Saber's CCO says there is absolutely no genAI in Space Marine 3 or Jurassic Park. Saber's own small game used it. The licence holder is the dividing line.
Amplitude shot its Gamescom trailer at Nu Boyana with 25 actors, 150 crew and a pig. The internet called it AI slop anyway, and the reasons are worth reading.
Hugging Face put 207 WGSL kernels on the Hub on 1 September. The geometric mean is 2.57x. Matmul, which dominates inference time, came in at 1.14x.
Nvidia confirmed the $12.93 billion deal on 3 September. The models your local tools fetch on install now come from a repository the chip vendor owns.
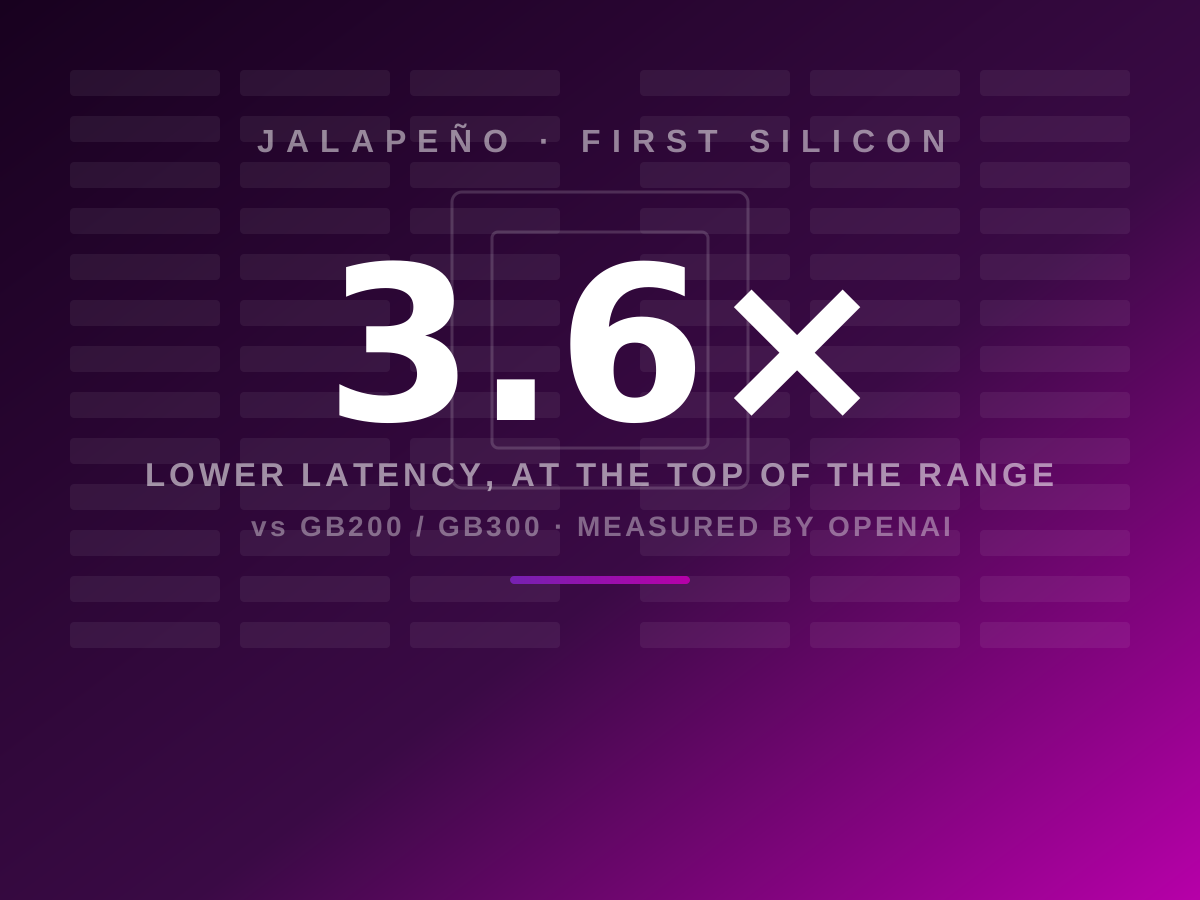
Jalapeño's first silicon results landed on 25 August — three open-weight models, two Nvidia rack generations, and a benchmark platform that isn't MLPerf.
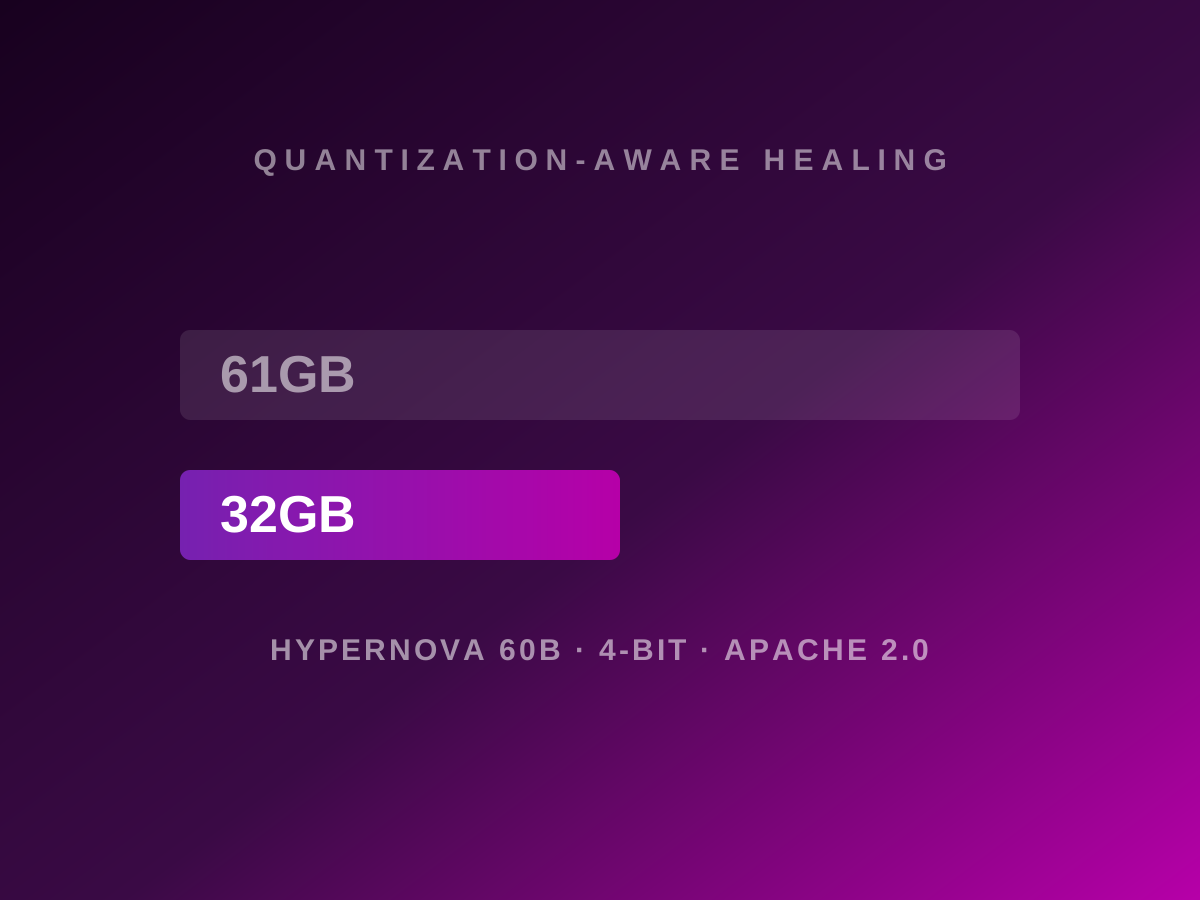
Multiverse took HyperNova 60B from 61GB to 32GB of VRAM with Quantization-Aware Healing, and the smaller model holds its ground against the original.
A "Seems like AI slop" button has been clicked over a million times since July, and LinkedIn says it's already suppressing reach by 40%.
OpenAI says its no-retention promise will survive the next generation of frontier models, via a new architecture it calls Private Safety Processing.
A 1M-token, image-and-video-reading model at half its old price, three weeks after the last one.
Ultrafast mode runs GPT-5.6 Sol at up to 750 tokens a second on Cerebras silicon, which matters most for a model that keeps pace while you work.
Not concept-to-final-render. The useful places are smaller, less glamorous, and they compound.
May I count this visit? Google Analytics would set cookies to tell me which pages get read. Nothing is measured unless you say yes. Privacy